Unit Cost Curves as LLM Inference Scales From 10 to 10,000 GPUs
Scaling LLM inference isn't linear: utilization and scheduling matter more than GPU count.
Dae-Jung Kwon
Contributing Writer, Scaling & Finance
A former quantitative analyst turned technology writer, Dae-Jung has spent more than a decade mapping the intersection of unit economics and engineering decisions at hyperscale and startup alike. His reporting draws on primary interviews with infrastructure leads and investors across the US and East Asian markets.
4 stories
Scaling LLM inference isn't linear: utilization and scheduling matter more than GPU count.
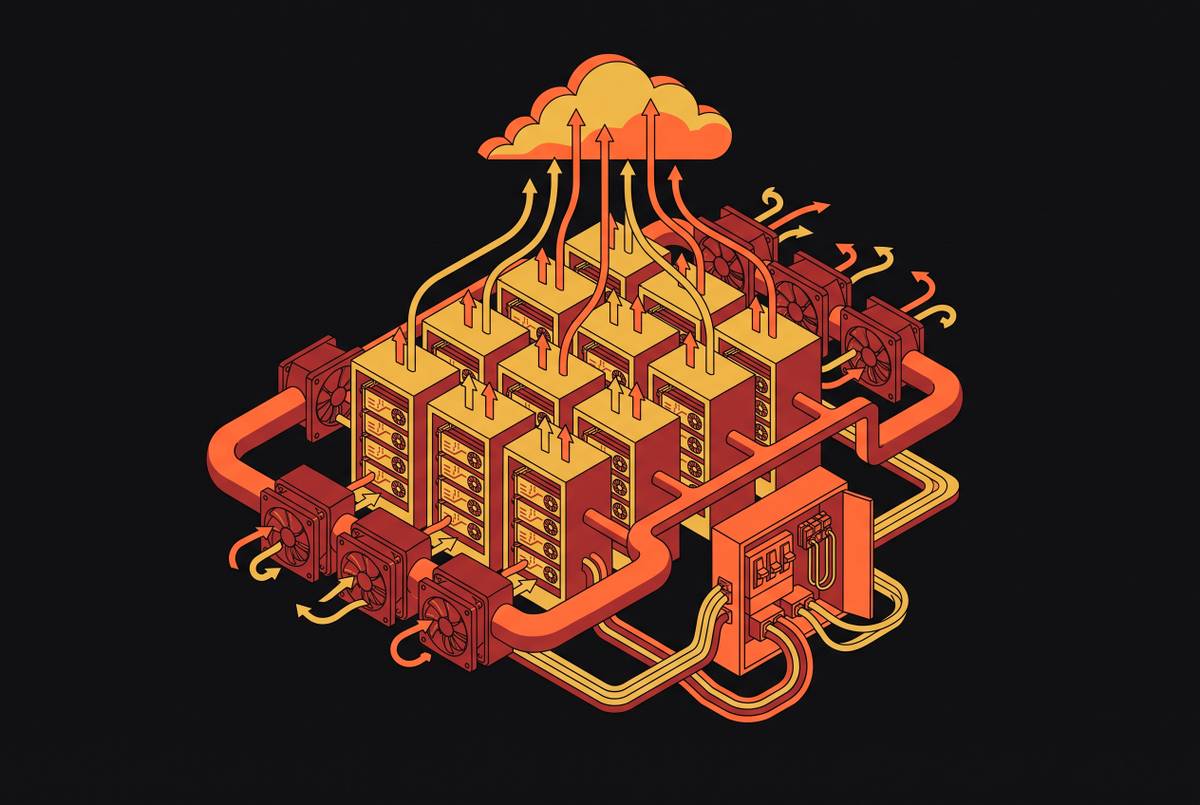
Power and cooling infrastructure now costs as much as the GPUs themselves.
KV cache transfers between GPU pools drive network costs more than computation or model size.
Model weights are cheap; the infrastructure, staffing, and operations bill is what blindsides teams.