Storage Throughput Bottlenecks That Blow Up Your Per-Token Cost at 128k Context
Storage I/O speed, not GPU compute, determines whether long-context serving stays cost-efficient.
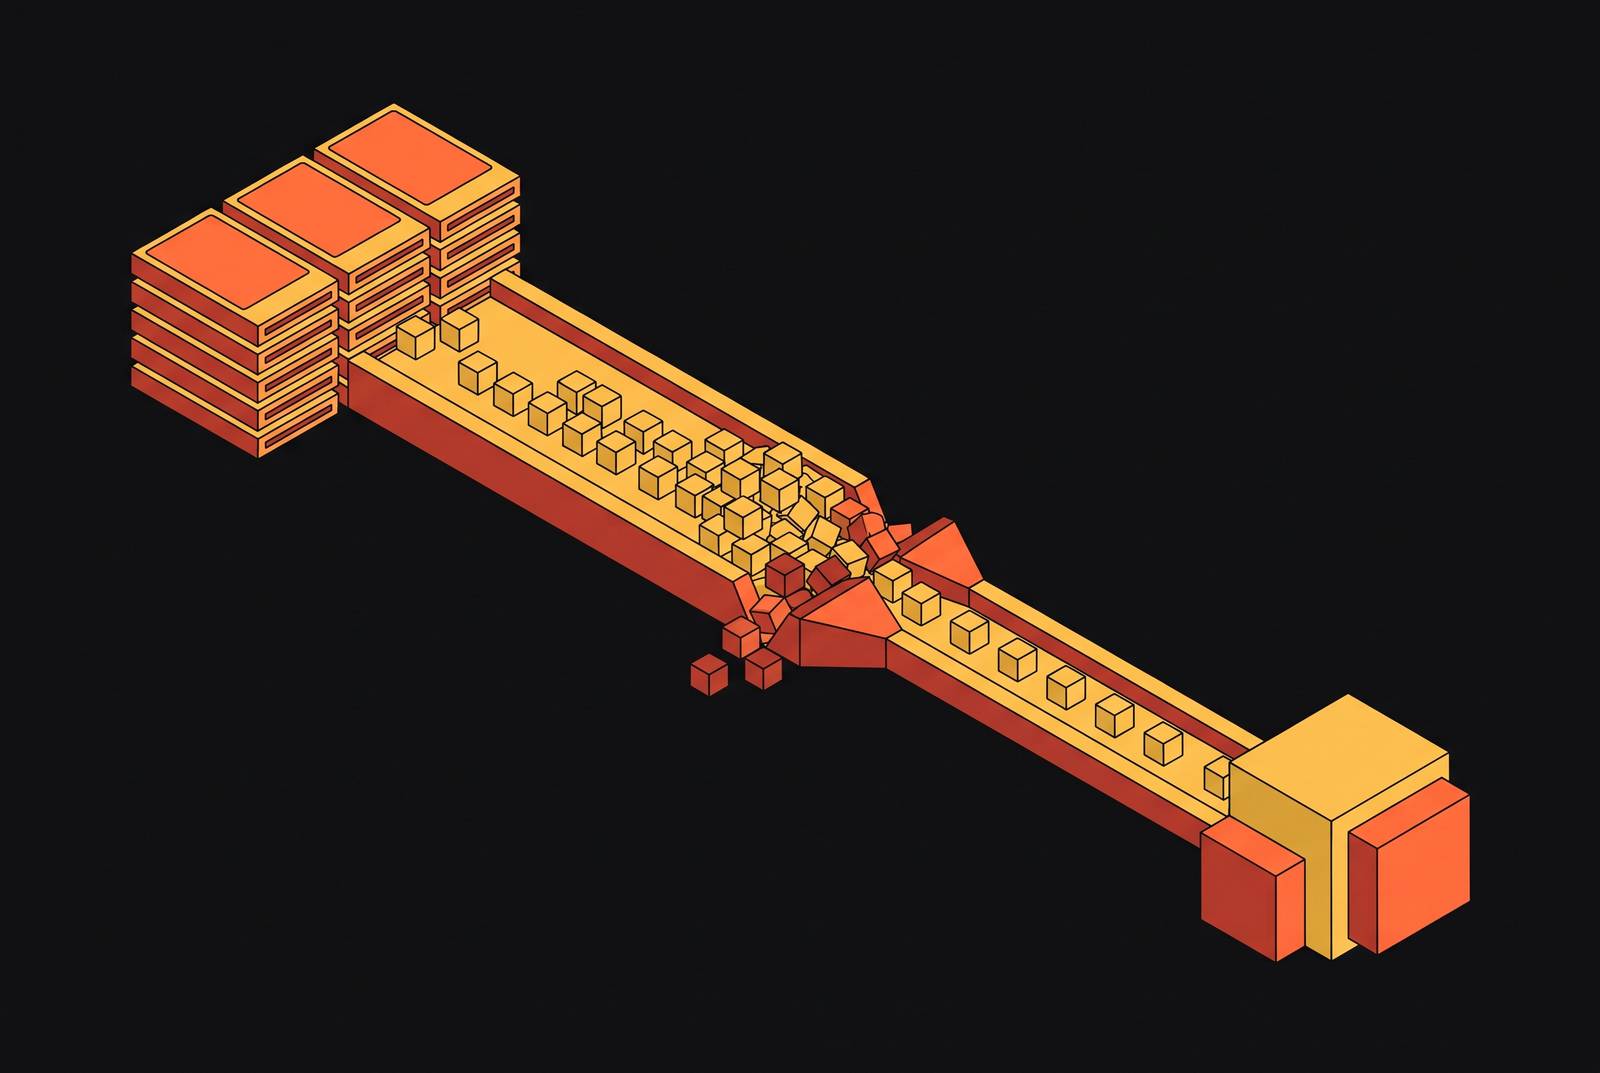
Serving LLMs at 128k context or longer requires both sufficient GPU compute and a KV-cache-aware memory and storage stack. Per-token cost rises when cache movement across HBM, PCIe, inter-node links, and NVMe leaves paid GPU capacity waiting for data. The right infrastructure addresses the binding constraint at each layer, combining capacity expansion with format-aware compression, appropriate interconnects, and purpose-built cache I/O.
Why per-token cost at 128k context is a storage problem, not just a compute problem
Model size and GPU spend explain only part of what it costs to serve long-context requests. KV cache memory grows linearly with both context length and batch size, so longer prompts and more concurrent users compete for the same finite HBM capacity. That competition constrains how many requests a GPU can serve together. Batch occupancy falls as individual caches grow. Once caches move outside GPU memory, the cost of retrieving them can overwhelm the computation that offloading was meant to support.
The economic penalty comes from reduced useful output per GPU-hour. A GPU waiting for cache data still costs money, but the fixed cost is spread across fewer generated tokens. Adding more storage capacity does not by itself bring throughput back up. HBM bandwidth, PCIe transfer rate, inter-node bandwidth, and NVMe restoration latency impose distinct constraints on how quickly cached state becomes usable. Each can become a cost multiplier even after the preceding layer has been improved.
How the KV cache actually fills the memory hierarchy, layer by layer
Prefill generates key and value tensors for every input token, while decode reads those tensors on every autoregressive step. At long context, state must be kept and then supplied again and again as fast as generation needs it. HBM has bandwidth measured in TB/s, but there is a limit to how much state it can hold close to the GPU. Once concurrent caches exceed that capacity, serving must navigate slower tiers.
CPU DRAM expands the available memory pool, but GPUs access it over PCIe at tens of GB/s. Local NVMe adds capacity behind sequential reads in the low GB/s range, while remote nodes and networked storage depend on the interconnect fabric. Each step introduces a narrower data path. Meng et al.'s bottleneck analysis documents the HBM-to-PCIe gap, where transfers that take milliseconds from HBM take hundreds of milliseconds from CPU DRAM. The hierarchy imposes a physical constraint on serving.
Better allocation preserves scarce HBM without removing that constraint. PagedAttention reduced fragmentation waste to under 4%, whereas contiguous allocation previously wasted the majority of VRAM. Prefix caching solves a different problem by avoiding redundant prefill computation on cache hits, but it does not shrink the cached tensors themselves. A miss still incurs full prefill cost, so neither technique eliminates the cost of moving cached tensors across slower tiers.
What happens when PCIe becomes the critical path — GPU underutilization as a cost signal
Meng et al. define κ_crit as the cached-to-prefill token ratio at which execution crosses from compute-bound to memory-bound. In plain terms, enough reused context makes moving existing state slower than computing the new input. Their analysis finds typical production workloads beyond that crossover by orders of magnitude. Conversation workloads are already well above the hardware threshold. Document-query workloads have more cached material for each new input token, so they are even further above it.
The same analysis finds that GPUs use only 28% of their rated thermal design power on average while serving offloaded requests. The GPU has been purchased, but transfer waits prevent much of its compute capacity from producing tokens. PCIe 5.0 provides 64 GB/s, a small fraction of HBM bandwidth. A long-document Q&A request on a large model can require tens of gigabytes to cross that link, creating a stall measured in hundreds of milliseconds.
Scheduling cannot necessarily reclaim that wait window because the GPU is blocked from additional compute while the transfer completes. Low batch occupancy compounds the loss of useful work. More VRAM or fewer concurrent sessions can postpone the constraint, but even modest long-context concurrency exhausts HBM at production batch sizes. Provisioning alone does not remove the bandwidth mismatch. Meng et al. identify NVLink C2C and unified HBM architectures as hardware levers that raise the crossover threshold, while MLA attention reduces the model's demand for cache data.
How prefill–decode disaggregation solves one bottleneck and creates another
Prefill–decode disaggregation separates compute-saturating prefill from memory-bandwidth-saturating decode. When the phases run together, each can starve the other and cause latency spikes that show up most clearly at p99. Separation removes that source of interference. vLLM, SGLang, TensorRT-LLM, LMDeploy, and NVIDIA Dynamo support disaggregation, while DeepSeek and Gemini deploy it at production scale.
The decode worker must receive the tensors produced by prefill before generation can begin. At long context, that handoff can dominate time-to-first-token over typical inter-cluster bandwidth in the tens to low hundreds of GB/s. The interconnect choice is therefore consequential. In a production KV-handoff experiment, switching from TCP to RDMA cut p50 time-to-first-token to roughly 720 ms, with output throughput nearly doubling. RDMA with GPU-Direct can hide the transfer behind scheduling overhead, whereas an unhidden transfer remains on the request's critical path.
For fewer than roughly 8 GPUs per model, or for short prompts, serialization and transfer can cost more than the prefill computation they help separate. Co-located chunked prefill is the better choice in that situation. Multi-turn and agentic workloads present another limitation because the disaggregated path is directional, with prefill producing state and decode consuming it without a reverse channel. Each new turn re-traverses the full pipeline rather than resuming from shared state, renewing pressure to retain and restore caches beyond HBM.
Why the NVMe tier fails as a naive KV offload destination
When concurrent caches fill CPU DRAM as well as HBM, NVMe becomes the local capacity tier that can preserve them without recomputation. Capacity alone is insufficient for active serving, however, because restoring the cache must still fit the request's latency budget. Tutti's 2026 research found that KV restoration remained highly inefficient even with GPU Direct Storage enabled because GDS left the CPU on the critical I/O control path. Tutti was designed to remove that bottleneck as well as bypass a data-copy step.
Restoration stalls can negate the throughput benefit of retaining the cache at all. That makes naive NVMe offloading difficult to justify under latency-sensitive SLOs. DRAM-resident caching with eviction and recomputation is a legitimate trade-off that can require less engineering than correctly managing SSD-tier I/O. It stops being enough when the context lengths and concurrency that serving needs fill DRAM itself.
NVIDIA's Inference Context Memory Storage Platform, announced at CES 2026, targets this control-path gap with BlueField-4 hardware-accelerated cache placement that removes metadata overhead from the CPU path. DOCA, Dynamo, and NIXL handle accelerated KV sharing across AI nodes through HBM, DRAM, and direct-attached and networked NVMe. Mooncake, developed by Moonshot AI / Kimi and awarded FAST 2025 Best Paper, treats KV cache as a first-class resource across GPU memory, CPU DRAM, and SSD. Its open-sourced Transfer Engine supports RDMA, TCP, NVMe-oF, NVLink, and other protocols for inter-node movement. Mooncake entered production at Kimi processing over 100 billion tokens daily across thousands of nodes, illustrating the scale at which cache-specific storage engineering becomes necessary.
Reducing KV size through quantization and compression — what the format choice actually costs
Lowering KV precision from BF16 to FP8 or below reduces the bytes that must cross every constrained boundary. NVFP4 halves KV memory requirements relative to FP8 and has appeared in production MLPerf submissions, but its reduced numerical range and more complex calibration prevent it from being a drop-in replacement. How much accuracy is lost depends on the workload. A smaller cache is useful only if the resulting behavior remains acceptable for the deployment.
More aggressive approaches, including SnapKV, KIVI 2-bit, ChunkKV, and Ada-KV, reduce retained state or its precision further but can produce outputs that differ non-deterministically from full-precision inference. VeriCache's 2026 work treats this as a concern about correctness in regulated or high-stakes deployments, beyond the trade-off in accuracy scores. Eviction research is also becoming more selective. Jacap's September 2026 paper models attention as a nonlinear information channel and uses a local sensitivity-based Nonlinear Information Capacity objective to account for softmax competition that token-isolation heuristics miss. The paper reports better performance in most scenarios at high compression ratios on LongBench, NIAH, and AIME25, but the state kept after eviction still needs bandwidth.
BF16 and FP8 differ in alignment and numerical-range properties, so they need compression and I/O pipelines built for those formats. General-purpose paths optimized for FP32 or INT8 do not correctly serve these formats at the throughput KV serving requires. MLPerf Storage v3.0, released in September 2026, adds KV cache and vector database workloads plus an S3 data layer to the existing POSIX interface, giving practitioners the suite's first standardized coverage of KV offloading.
What infrastructure do you need for long-context LLM serving at scale?
At the PCIe layer, shared-prefix reuse through SGLang RadixAttention can reduce transfer volume when reusable state is available, without reducing the size of the underlying tensors. When hit rates are high, this can cut transfers for few-shot, document Q&A, and multi-turn workloads before any change to the hardware. Saving on transfers still depends on cache locality. NVLink C2C and unified HBM architectures address the hardware boundary, while cache-size reduction lowers the demand placed on it.
For disaggregated deployments, RDMA with GPU-Direct is the appropriate default, while co-located chunked prefill remains preferable when small clusters or short prompts make transfer overhead exceed compute savings. DualPath's 2026 work targets a storage-bandwidth imbalance in which prefill-side storage NICs saturate while decode-side NICs remain idle. Its dual-path KV-Cache loading improves offline inference throughput by up to 1.87× and online serving throughput by an average of 1.96×. This targets the inter-node and HBM-reload boundary together rather than assuming that separation alone balances the system.
At the SSD tier, the relevant engineering patterns are hardware-accelerated cache placement, as in ICMSP, and RDMA-based transfer engines, as in Mooncake. Naive GDS offloading without removing CPU control-path bottlenecks does not solve restoration stalls. Storage sizing must therefore account for retrieval throughput under concurrent long-context load, with the benchmark's KV workload providing a measurement framework. Device capacity is not a serving guarantee. At 128k context and beyond, viable storage is designed around KV access patterns, AI-native formats, and the bandwidth of the entire memory hierarchy, rather than general-purpose NVMe capacity or standard file I/O alone.
Sources
- Understanding Bottlenecks for Efficiently Serving LLM Inference With KV Offloading
- KV CACHE OPTIMIZATION STRATEGIES FOR SCALABLE AND EFFICIENT LLM INFERENCE
- Jacap: Robust KV Cache Eviction via Jacobian-Based Nonlinear Information Capacity Preservation
- VeriCache: Turning Lossy KV Cache into Lossless LLM Inference