When the Inference Stack Hits the Memory Wall What Actually Breaks First
KV cache overflow comes first, then PCIe, then idle GPUs.
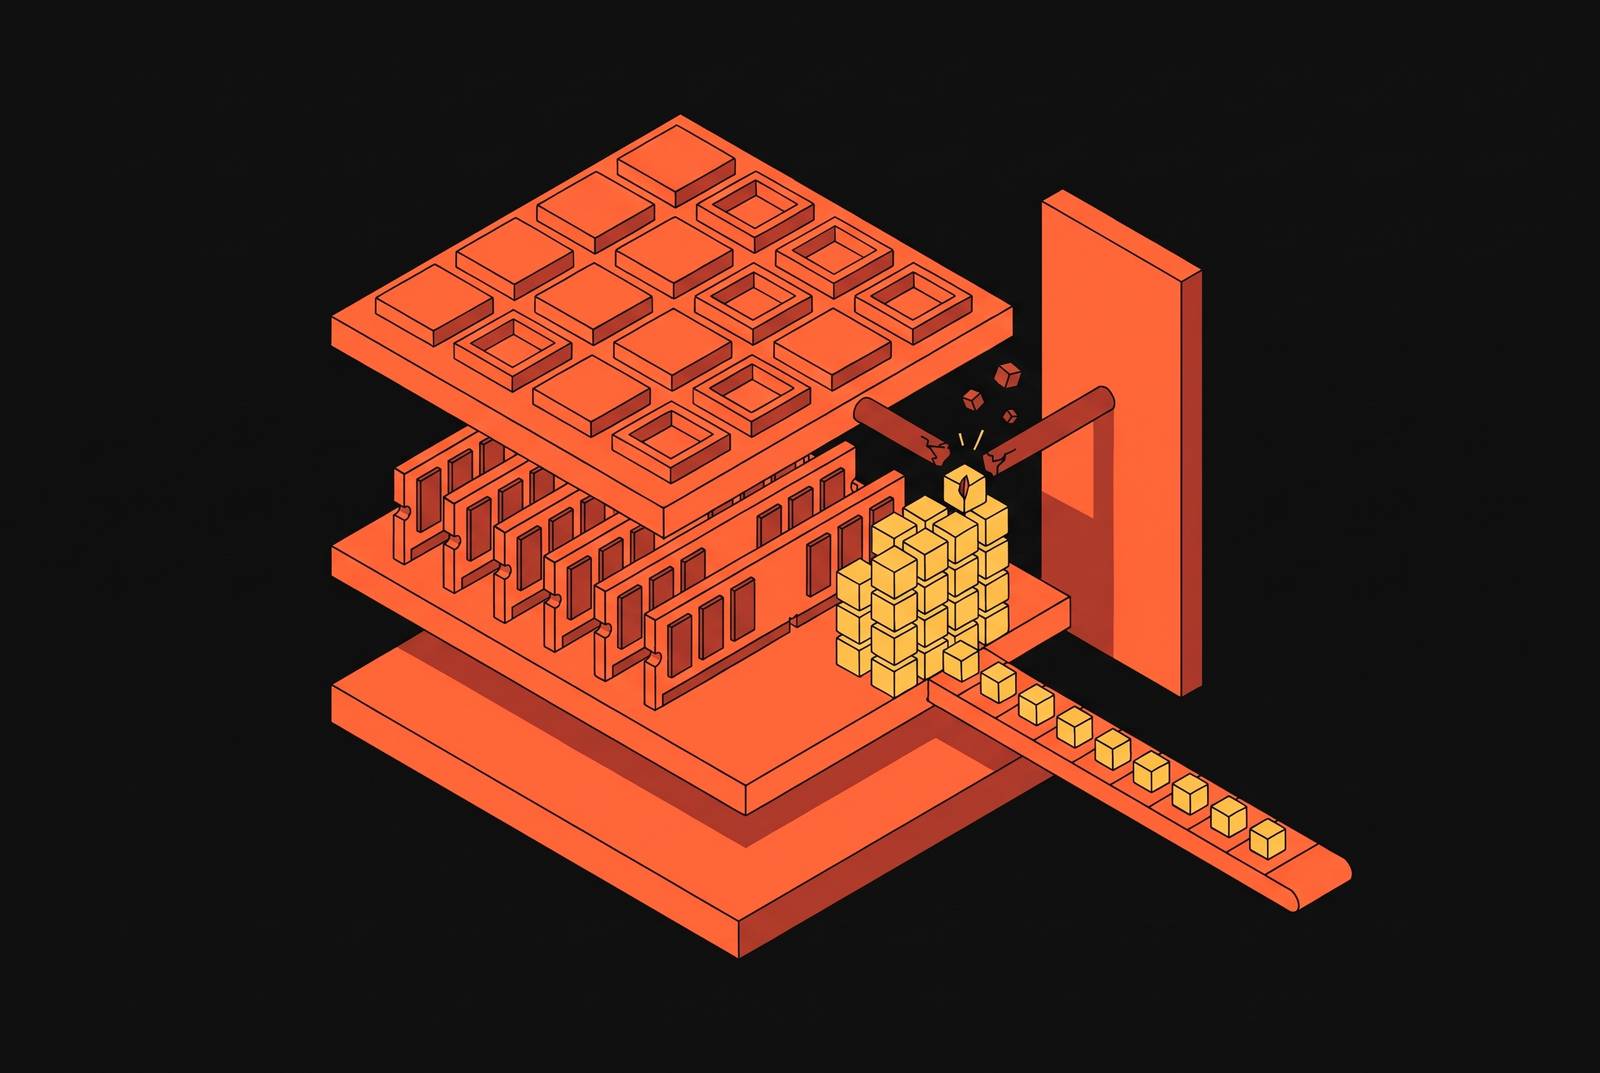
Long-context LLM serving requires memory sized for active KV state, a tiered cache hierarchy, and storage bandwidth matched to context length and concurrency. The memory wall follows a predictable sequence, from KV cache overflow to PCIe transfer dominance to idle GPUs. Offloading interrupts that sequence only when cache reuse saves more computation than retrieval costs.
How KV cache memory scales and why it fills GPU memory faster than weight memory at long context
Model weights take up memory, but they do not grow as each request’s context grows. KV state does. The engine stores keys and values per layer, per attention head, and per token, so cache memory grows linearly with sequence length, batch size, model width, and number of layers. At FP16/BF16 precision, a large model can require hundreds of kilobytes of KV storage per token. A single long-context session can therefore approach tens of gigabytes before concurrency enters the calculation.
On an H100 serving a large model at long context, one user’s KV cache can consume tens of gigabytes. A handful of concurrent users can require several times the GPU’s entire HBM capacity. Weight fit is therefore an incomplete sizing criterion. HeadInfer demonstrates the same imbalance for a smaller model, where generating a very long sequence requires hundreds of gigabytes in total and KV cache accounts for the dominant share. Model weights take up only a small share of that memory.
Prefill computation is quadratically expensive in sequence length, while retained KV memory grows linearly. The engine must first compute the context and then find space to preserve it. Once that space runs out, the expensive computation becomes vulnerable to repetition.
What the inference engine does when VRAM fills: eviction, preemption, and the recompute-or-reload decision
vLLM’s PagedAttention manages KV state in fixed-size, non-contiguous blocks, analogous to pages in virtual memory. This organizes allocation but does not create capacity. When GPU memory is exhausted, the engine preempts a running request and discards its KV values from GPU memory. The request must then recompute those values when rescheduled. For long-context requests at 2026 context lengths, doing the full prefill over and over can take up most of the GPU time and directly cut throughput.
The alternative is to move KV blocks into CPU DRAM asynchronously before preemption. That preserves computation but creates a reload dependency. When the request resumes, its cache must return to the GPU before the dependent work can proceed. Under concurrency, the engine is therefore forced to trade repeated computation against transfer latency, with neither path providing a cost-free fallback. Which penalty is smaller depends on context length, cache hit rate, and GPU speed.
The py-kvcache paper shows why that decision cannot be universal. On an H100, average requests in the Bailian production trace are below the external-cache break-even point because GPU memory already holds enough prefixes. External caching adds latency for those short-prefix requests. Agentic workloads sit at the opposite extreme, because a session that suspends during a tool call may otherwise pay the full prefill cost again on resumption. Persistence has value when it preserves substantial work.
Why PCIe bandwidth becomes the dominant latency term once offloading begins
Once KV blocks spill into CPU DRAM, the bottleneck moves from memory capacity to the link returning them. HBM delivers terabytes per second, while CPU-GPU PCIe 5.0 delivers roughly 64 GB/s. The bandwidth gap is steep and consequential. A cache can fit with room to spare in host memory but still take too long to reload for the next request.
Local NVMe has still less bandwidth, with roughly 7–7.4 GB/s on a PCIe 4.0 device whose theoretical limit is approximately 7.88 GB/s. Access latency ranges from hundreds of microseconds to milliseconds, compared with sub-microsecond HBM access. Traditional CPU-staged I/O also needs to copy data more than once between storage and GPU memory. Each copy consumes bandwidth and adds latency to the critical path. The useful comparison therefore covers the complete retrieval path.
vLLM 0.11.0’s asynchronous offloading connector overlaps KV transfer with request scheduling while keeping the engine running. It hides offload write latency, while cache-hit reloads cut time-to-first-token by a factor of two to twenty-two depending on prompt size. Scheduling determines how much transfer remains exposed. The py-kvcache study finds that transfer granularity, intermediate memory use, and transfer timing influence performance beyond raw bandwidth. Its scheduler-aware preloading starts disk reads while requests remain queued and is measurably faster at long context than waiting until those requests need the data.
How GPU idle time accumulates as storage transfers dominate the critical path
During prefill with an offloaded cache, attention computation cannot begin until the required KV blocks arrive. If transfer takes longer than the computation would have taken, the GPU stalls. That is where memory pressure becomes operating cost. GPU capacity is still tied up in serving, but the compute units cannot do the work that depends on those blocks. Repeated reload waits reduce the useful throughput obtained from that capacity.
Training checkpointing exposes the same economic problem through a different operation. Writing a large BF16 checkpoint through a CPU-staged path ties up GPU time that could otherwise go to forward or backward passes. Checkpoint frequency multiplied by checkpoint duration can consume a substantial fraction of total training time. In both cases, elapsed storage time displaces productive computation. Device throughput alone does not show how much compute time is lost.
HeadInfer reduces GPU memory usage by offloading individual attention heads and asynchronously overlapping KV movement between GPU and CPU. It helps only when there is still useful work to do during transfer. SlimInfer instead uses dynamic token pruning to identify active KV blocks for prefetch while inactive blocks remain offloaded. Its asynchronous cache manager cuts movement that is not needed, memory use, and I/O cost, which lowers time-to-first-token and end-to-end latency for long-context requests on a single GPU.
What infrastructure is needed to serve long-context LLMs at scale?
The structural response is a four-tier hierarchy that treats KV cache as distributed state. GPU HBM holds hot, active-session blocks and provides sub-microsecond access at the highest cost per gigabyte. CPU DRAM provides the next offload tier, preserving blocks outside GPU memory while requiring transfer across PCIe for reuse. These tiers solve different parts of the problem. HBM serves active computation, while DRAM offers additional retention at the cost of reload latency.
Local NVMe holds cold sessions and long-tail prefixes. Capacity is fairly easy to add, but the steady flow of write-heavy KV traffic is limited by endurance and write bandwidth. Datacenter-class high-DWPD drives and multiple drives for parallelism are required. Shared network storage or object storage is the fourth tier and lets caches move across the serving fleet. That portability enables a decode worker on one node to reuse a prefix computed by a prefill worker on another.
LMCache supports eight additional storage backends, eleven total, across four processor types and two inference engines. The serving engine must choose which blocks to keep in each tier and when to move them. The infrastructure team must provision the capacity and transfer paths that make those decisions viable. Correct placement cannot compensate for an underprovisioned path, just as fast storage cannot compensate for poor scheduling.
Where the tiered architecture itself breaks down: the network storage and RDMA layer under high concurrency
At high concurrency, requests also compete for shared storage. KV blocks must reach the GPU that needs them, and fabric bandwidth and copy overhead can become the constraint even when storage capacity is ample. Traditional CPU-staged paths use bandwidth to make intermediate copies. GPUDirect Storage establishes a direct DMA path between storage and GPU memory, bypassing CPU and system RAM. RDMA similarly removes the CPU from the data path for networked KV retrieval.
The appropriate path still depends on the operation. A SIGMETRICS 2026 study compared libaio, io_uring, SPDK, and GDS and found that io_uring achieved the lowest latency and competitive IOPS for small random NVMe I/O, an inference-dominant pattern. GDS cut model load times and CPU usage by a large amount for the large sequential transfers used in pre-training and fine-tuning. Direct access is not a universal performance ranking. Which path helps depends on the shape of the transfer and the phase of execution.
A DGX SuperPOD environment with a 400 Gbps RDMA fabric demonstrated a large reduction in long-context time-to-first-token when loading precomputed KV cache. The result depended on the combined operation of the fabric, BlueField-3 DPUs, and GPUDirect Storage. NVIDIA’s Inference Context Memory Storage Platform, announced at CES 2026, addresses this coordination through BlueField-4 DPUs that manage KV movement off the GPU compute path. NIXL provides its KV block transport protocol.
Why cache hit rate is the variable that determines whether the entire offloading architecture pays off
A faster retrieval path does not guarantee that retrieval is worthwhile. The py-kvcache paper makes the break-even condition explicit by comparing avoided GPU prefill against cache lookup, disk or host-memory reads, and CPU-to-GPU transfer. Short prompts leave little computation to avoid. Low hit rates reduce opportunities for reuse, while fast GPUs make recomputation harder to beat. The relevant success criterion is saved execution time.
Multi-turn assistants, RAG at scale, agentic loops, and code assistants repeat context often enough that it can be worth keeping. Conversation prefixes recur across turns, system prompts and document prefixes recur across users, and repository context repeats across keystroke bursts. Agent sessions also resume after tool calls. One-shot unique-prompt batch classification and single-question answering without repeated context have no such reuse. For those workloads, the cache infrastructure adds overhead without a throughput return.
Admission must therefore be set for each request or workload. Lossless compression can also help keep more data while leaving what the GPU receives unchanged. BF16 KV tensors have skewed exponent distributions that lossless entropy coders can exploit, with techniques such as GAAC demonstrating compression across tested models. Because retained capacity influences hit rate, compression can change the economics of the hierarchy while preserving output quality.
What the failure sequence means for how inference infrastructure should be specified and benchmarked
Infrastructure planning requires specifying context length and concurrency before translating model size into a GPU requirement. Memory planning must explicitly include KV capacity in DRAM, NVMe, and shared storage alongside weight fit. Transfer performance belongs in the same specification. Write-heavy KV traffic requires datacenter-class high-DWPD NVMe and high-bandwidth fabric. GPU count alone cannot describe a system whose critical path includes cache retrieval.
KV reload performance and checkpointing belong on the same dashboard as GPU utilization because stalls expose the cost that aggregate utilization can obscure. MLPerf Storage v3.0, published September 1, 2026, added KV cache and vector database tests and opened the benchmark to S3 object storage for the first time. It provides a public comparison of inference-relevant storage workloads. The working group expects object-based storage to become a workable, and perhaps preferred, alternative to filesystem-based storage at trillion-token context scale.
Infrastructure teams should therefore test storage against their targets for context and concurrency, how much cache they reuse, and how long GPUs wait for the state they need. Public KV-cache benchmarks provide a basis for comparing systems against those requirements. Storage is now part of the inference specification. The acceptance test is not simply whether the model and cache fit, but whether retained state reaches the GPU soon enough to outperform recomputation.
Sources
- Building py-kvcache: A Performance Characterization of External KV Caching for vLLM with NVMe SSDs
- SlimInfer: Accelerating Long-Context LLM Inference via Dynamic Token Pruning
- Understanding Bottlenecks for Efficiently Serving LLM Inference With KV Offloading
- HeadInfer: Memory-Efficient LLM Inference by Head-wise Offloading